Playbook · AI · Technology
Your AI pilot worked. Why isn't it in production?
A pilot proves the model can do the task. Production needs five things the pilot was allowed to skip.
The demo went well. The model summarised the contracts, drafted the replies or sorted the tickets, and the room was impressed. Six months later it still runs in a sandbox, used by the two people who built it.
This is common enough to show up in surveys. In McKinsey's "The state of AI in 2025" (November 2025), 62% of organisations said they were at least experimenting with AI agents, and 23% said they were scaling them. In Forrester's "The State of Agentic AI in 2026" (3 June 2026), three-quarters of enterprise leaders said they were adopting agentic AI, while "only a minority" ran meaningful production agents beyond chatbots.
You may also have seen the claim that 95% of AI pilots fail. It comes from an MIT NANDA report (July 2025) that is not peer-reviewed, rests on a small sample and measures something narrower than failure. We leave it aside. The gap is visible without it.
What a pilot is allowed to skip
A pilot answers one question: can the model do this task at all? It is built to say yes quickly. So it runs on clean examples, one enthusiastic team and no cost limit, and nobody has to change how they work.
Production asks different questions. Will it hold up on the messy inputs that arrive on a Tuesday afternoon? Who notices when it's wrong? Who changes their day because it exists? Who pays for it at a thousand times the volume?
None of these are model questions, and a better model won't answer them. They are questions about the business, and they need someone to decide.
The five gaps
Pilot to production: five gaps.
| Gap | What the pilot proved | What production needs |
|---|---|---|
| Real data | It works on examples someone chose. | It holds up on a week of real, unselected inputs. |
| A definition of good | The output looked right in the demo. | A written standard, checked against 20–50 real cases every time the system changes. |
| A changed workflow | One team tried it alongside their usual work. | Decided steps that disappear, change or move to someone else. |
| An owner | The people who built it looked after it. | A named owner in the team that uses it. |
| Cost at volume | Nobody counted the cost. | A monthly cost that includes the people who check the output. |
If any row is still open, the pilot is not ready to scale.
1. Real data
The pilot used examples someone chose. Production gets everything: scanned PDFs, half-filled forms, three languages. Test on a week of real, unselected inputs before anything else.
2. A definition of good
"It looks right" is not a standard. Write down what a good output is and what a bad one looks like, then check the system against it every time it changes. Anthropic's engineering team suggests that "20-50 simple tasks drawn from real failures is a great start" ("Demystifying evals for AI agents", 9 January 2026). That is a spreadsheet, not a research programme.
3. A changed workflow
If the AI produces a draft but the process still expects someone to start from a blank page, the draft gets ignored. McKinsey's report found that the small group of high performers, about 6% of respondents, were far more likely to have redesigned workflows. Decide which steps disappear, which change and who does them.
4. An owner
Someone has to watch quality, handle complaints and decide when it gets updated. A pilot belongs to the people who built it. A production system needs a named owner in the team that uses it.
5. Cost at volume
Price a normal month, not a demo afternoon. Include the model, the people who check the output and the time spent on the cases it gets wrong.
An example from our own work
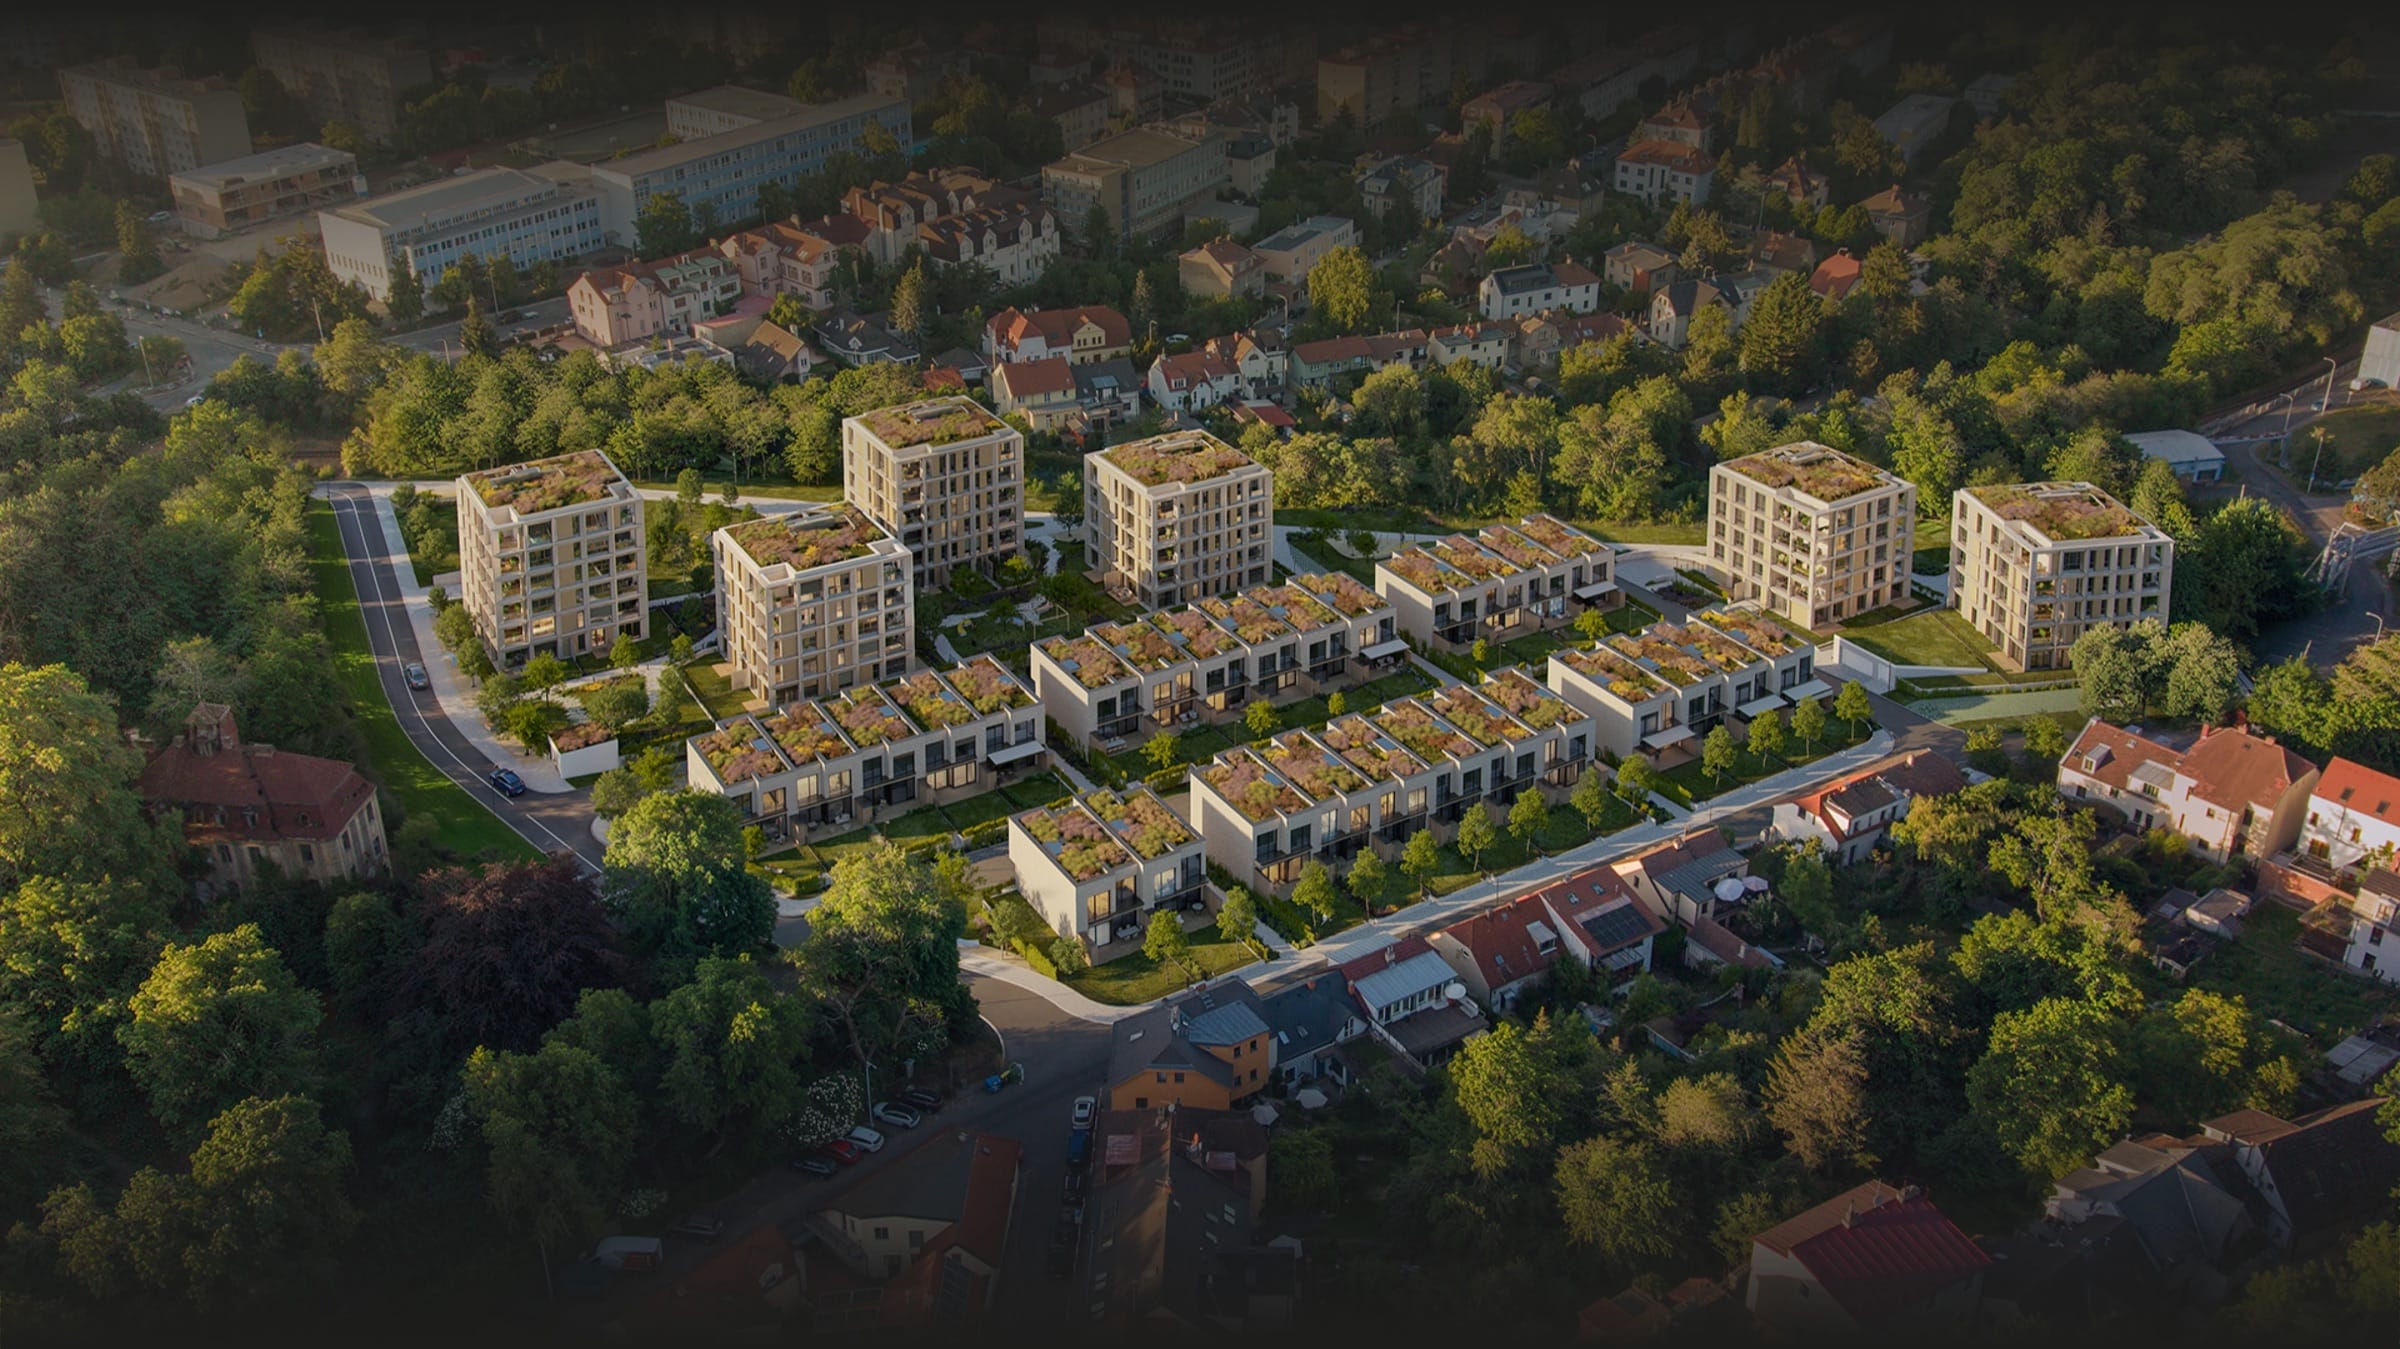
The BRIQUE sales plans we built for Penta Real Estate are an automation, not AI, but they cleared the same gaps. Plans drawn by hand went out of date with every design revision, and the sales team still had to sell from them. We set one plan style first, then made it possible to redraw every plan whenever the design changed. A plan is only useful while it is current, so keeping up with the design mattered as much as how it looks. The plans now cover 114 apartments across six buildings.
Illustrative example, not a Flygen client. A legal team pilots contract summaries on twenty agreements, and they are good. In production, a third of incoming contracts are scans with handwritten amendments, and nobody has said whether a summary replaces the first read or only speeds it up. Two weeks of real inputs, a checklist of what a summary must never miss and one decision about the workflow move it further than a better model would.
What to do Monday
- Pick your most promising pilot and write the five gaps down as questions. Mark each one answered, partly answered or open.
- Collect a week of real inputs, unselected, and run the pilot on them.
- Write down 20 examples of good and bad output, and agree who judges them.
- Name the owner in the team that will use it.
- Put a monthly cost on it, including the people who check it.
AI makes the pilot cheap. Deciding what the system is for, and what good looks like, is where the value is. That is the work of our AI & Agentic Systems service.
Where this leadsAI & Agentic Systems
Tools for better decisions
AI Opportunity Scorecard
Ten questions about one task. You see the verdict, the best mode and the human role straight away.
Run the scorecardAI Product Quality Canvas
Eight boxes that pin down what an AI feature should do, how it fails and how you will know it works.
Open the canvas